Vector Databases, Semantic Search & RAG Data Layer
Business Scenario
Welcome!
Previously, explored the RAG ingestion, retrieval, and generation. Loaded PDF, Word, web, and CSV data into LangChain documents, compared chunking methods, and stored and searched chunks in Chroma with metadata filters. You compared Chroma with FAISS, reloaded and updated the saved index, built smartcart_rag_data.py, measured retrieval hit rate.
Today, your manager has assigned you a task to connect Kart to SmartCart's RAG system. You will make Kart answer questions using the actual return policy and product catalogue, recommend products at real prices, and admit when the required information is unavailable instead of guessing.
Git Pull
git pull origin branchNamePre-Lab Preparation
Dataset :
Topic : Build Chatbot V3 - Full RAG Integration
1) Generation of RAG
2) Grounded Answers
3) Citing Sources
Task 1: Setup — Bring In the Pieces from Earlier Labs
import os

needed = ["SmartCart_Return_Policy.pdf", "SmartCart_Delivery_FAQ.docx", "smartcart_products.csv"]

for name in needed:
    if os.path.exists(name):
        print("OK      ", name)
    else:
        print("MISSING ", name, "-- upload it with the folder icon on the left")
Upload data files
1
Output
Install the libraries
2
!pip install -q langchain langchain-groq langchain-ollama langchain-community \
    langchain-text-splitters langchain-chroma langchain-huggingface \
    sentence-transformers pypdf docx2txt beautifulsoup4
from google.colab import userdata
os.environ["GROQ_API_KEY"] = userdata.get("GROQ_API_KEY")
print("Key loaded:", os.environ["GROQ_API_KEY"][:4] + "...")Load the API Key
3
Define RAG Data Layer (copied from Lab 15)
4
os.environ["USER_AGENT"] = "SmartCartLab/1.0"

from langchain_community.document_loaders import (
    PyPDFLoader, Docx2txtLoader, WebBaseLoader, CSVLoader)
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_huggingface import HuggingFaceEmbeddings
from langchain_chroma import Chroma

DB_FOLDER = "smartcart_db"
SOURCES = [
    ("SmartCart_Return_Policy.pdf", "policy"),
    ("SmartCart_Delivery_FAQ.docx", "faq"),
    ("https://en.wikipedia.org/wiki/Cash_on_delivery", "web"),
    ("smartcart_products.csv", "product"),]
embedder = HuggingFaceEmbeddings(model_name="sentence-transformers/all-MiniLM-L6-v2")
os.environ["USER_AGENT"] = "SmartCartLab/1.0"
from langchain_community.document_loaders import (
PyPDFLoader, Docx2txtLoader, WebBaseLoader, CSVLoader)
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_huggingface import HuggingFaceEmbeddings
from langchain_chroma import Chroma
DB_FOLDER = "smartcart_db"
SOURCES = [
("SmartCart_Return_Policy.pdf", "policy"),
("SmartCart_Delivery_FAQ.docx", "faq"),
("https://en.wikipedia.org/wiki/Cash_on_delivery", "web"),
("smartcart_products.csv", "product"),]
embedder = HuggingFaceEmbeddings(model_name="sentence-transformers/all-MiniLM-L6-v2")
def load_documents():
"""Stage 1 -- load every source and tag it with its doc_type."""
docs = []
for source, doc_type in SOURCES:
if source.endswith(".pdf"):
loader = PyPDFLoader(source)
elif source.endswith(".docx"):
loader = Docx2txtLoader(source)
elif source.endswith(".csv"):
loader = CSVLoader(source)
else:
loader = WebBaseLoader(source)
for doc in loader.load():
doc.metadata["doc_type"] = doc_type
docs.append(doc)
return docs
def chunk_documents(docs):
"""Stage 2 -- split documents into overlapping chunks of up to 300 characters."""
splitter = RecursiveCharacterTextSplitter(chunk_size=300, chunk_overlap=50)
return splitter.split_documents(docs)
def build_vector_store(chunks):
"""Stage 3 -- empty the database, then embed and store all chunks."""
store = Chroma(collection_name="smartcart", embedding_function=embedder,
persist_directory=DB_FOLDER)
store.reset_collection() # start empty -- safe to run again and again
store.add_documents(chunks)
return store
os.environ["USER_AGENT"] = "SmartCartLab/1.0"

from langchain_community.document_loaders import (
    PyPDFLoader, Docx2txtLoader, WebBaseLoader, CSVLoader)
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_huggingface import HuggingFaceEmbeddings
from langchain_chroma import Chroma

DB_FOLDER = "smartcart_db"
SOURCES = [
    ("SmartCart_Return_Policy.pdf", "policy"),
    ("SmartCart_Delivery_FAQ.docx", "faq"),
    ("https://en.wikipedia.org/wiki/Cash_on_delivery", "web"),
    ("smartcart_products.csv", "product"),]
embedder = HuggingFaceEmbeddings(model_name="sentence-transformers/all-MiniLM-L6-v2")

def load_documents():
    """Stage 1 -- load every source and tag it with its doc_type."""
    docs = []
    for source, doc_type in SOURCES:
        if source.endswith(".pdf"):
            loader = PyPDFLoader(source)
        elif source.endswith(".docx"):
            loader = Docx2txtLoader(source)
        elif source.endswith(".csv"):
            loader = CSVLoader(source)
        else:
            loader = WebBaseLoader(source)
        for doc in loader.load():
            doc.metadata["doc_type"] = doc_type
            docs.append(doc)
    return docs

def chunk_documents(docs):
    """Stage 2 -- split documents into overlapping chunks of up to 300 characters."""
    splitter = RecursiveCharacterTextSplitter(chunk_size=300, chunk_overlap=50)
    return splitter.split_documents(docs)

def build_vector_store(chunks):
    """Stage 3 -- empty the database, then embed and store all chunks."""
    store = Chroma(collection_name="smartcart", embedding_function=embedder,
                   persist_directory=DB_FOLDER)
    store.reset_collection()        # start empty -- safe to run again and again
    store.add_documents(chunks)
    return store
def get_retriever(k=3, doc_type=None):
"""Stage 4 -- open the saved database and return a retriever."""
store = Chroma(collection_name="smartcart", embedding_function=embedder,
persist_directory=DB_FOLDER)
search_kwargs = {"k": k}
if doc_type:
search_kwargs["filter"] = {"doc_type": doc_type}
return store.as_retriever(search_kwargs=search_kwargs)5
Build the Database (copied from Lab 15)
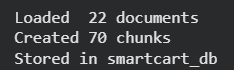
docs = load_documents()
print("Loaded ", len(docs), "documents")

chunks = chunk_documents(docs)
print("Created", len(chunks), "chunks")

build_vector_store(chunks)
print("Stored in", DB_FOLDER)
Output
Define get_llm() from Lab 13, now with json_mode switch
6
from langchain_groq import ChatGroq
from langchain_ollama import ChatOllama

CLOUD_MODEL = "qwen/qwen3.8-27b"     # GroqCloud, same model since Lab 7
LOCAL_MODEL = "qwen2.5:3b"           # Ollama, Lab 13

def get_llm(backend="cloud", json_mode=True):
    """Return the chat model for 'cloud' (GroqCloud) or 'local' (Ollama)."""
    if backend == "local":
        if json_mode:
            return ChatOllama(model=LOCAL_MODEL, temperature=0.3, num_predict=800, format="json")
        return ChatOllama(model=LOCAL_MODEL, temperature=0.3, num_predict=800)
    extra = {"response_format": {"type": "json_object"}} if json_mode else {}
    return ChatGroq(model=CLOUD_MODEL, temperature=0.3, max_tokens=800,
                    model_kwargs=extra, reasoning_effort="none")
Use the recursive splitter for every document
2
chunks = recursive.split_documents(all_docs)

print(len(all_docs), "documents ->", len(chunks), "chunks")
print("Chunk metadata:", chunks[0].metadata)
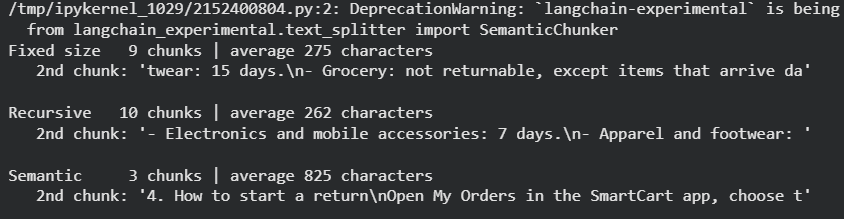
from langchain_text_splitters import CharacterTextSplitter, RecursiveCharacterTextSplitter
from langchain_experimental.text_splitter import SemanticChunker
policy_text = "\n".join(doc.page_content for doc in pdf_docs)
fixed = CharacterTextSplitter(separator="", chunk_size=300, chunk_overlap=0)
recursive = RecursiveCharacterTextSplitter(chunk_size=300, chunk_overlap=50)
semantic = SemanticChunker(embedder)
for name, splitter in [("Fixed size", fixed), ("Recursive", recursive), ("Semantic",
semantic)]:
chunks = splitter.split_text(policy_text)
average = sum(len(c) for c in chunks) // len(chunks)
print(f"{name:<10} {len(chunks):>3} chunks | average {average} characters")
print(" 2nd chunk:", repr(chunks[1][:70]), "\n")Output :
Output :
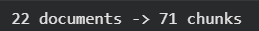
Task 4 : Store & Search in a Vector Database
from langchain_chroma import Chroma

vector_store = Chroma.from_documents(
    documents=chunks,
    embedding=embedder,
    collection_name="smartcart",
    persist_directory="smartcart_db")        # saved in this folder
print("Chunks stored:", len(vector_store.get()["ids"]))
Output :
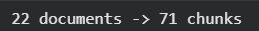
Build the Chroma index
1
Ask a shopper question
2
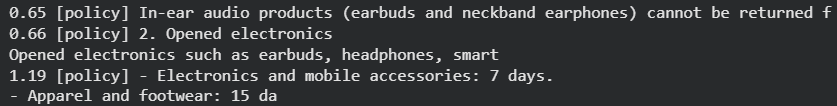
question = "Can I return earbuds after opening the box?"
results = vector_store.similarity_search_with_score(question, k=3)
for doc, distance in results:
 print(f"{distance:.2f} [{doc.metadata['doc_type']}] {doc.page_content[:75]}")
Output
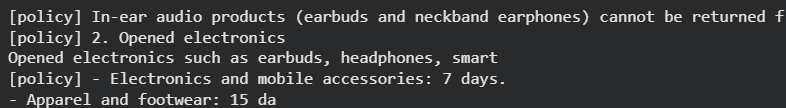
for doc in vector_store.similarity_search("earbuds", k=3, filter={"doc_type": "policy"}):
    print(f"[{doc.metadata['doc_type']}] {doc.page_content[:75]}")
Filter by metadata to search only one type of document
3
Output
from langchain_community.vectorstores import FAISS
faiss_store = FAISS.from_documents(chunks, embedder)
for doc in faiss_store.similarity_search(question, k=3):
    print(f"[{doc.metadata['doc_type']}] {doc.page_content[:75]}")
Build the same stage with FAISS
4
Output
Task 5 : Indexing & Querying at Scale
import time

start = time.time()
store = Chroma(collection_name="smartcart", embedding_function=embedder,
               persist_directory="smartcart_db")
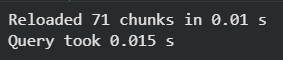
print(f"Reloaded {len(store.get()['ids'])} chunks in {time.time() - start:.2f} s")

start = time.time()
store.similarity_search("Is delivery free?", k=3)
print(f"Query took {time.time() - start:.3f} s")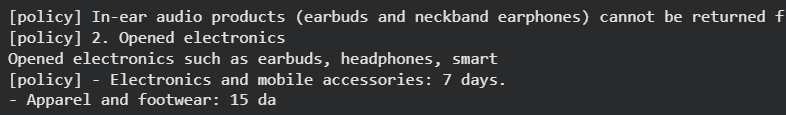
Reload the saved index and time a query
1
Output
Add a new document with an ID instead of rebuilding
2
from langchain_core.documents import Document

diwali = Document(
    page_content="Diwali Sale 2026: from 1 to 8 November,
    delivery is free on all orders "
    "and the return window for electronics is extended to 10 days.",
    metadata={"source": "announcement", "doc_type": "faq"},
)

store.add_documents([diwali], ids=["faq-diwali-2026"])
store.add_documents([diwali], ids=["faq-diwali-2026"])          # same ID again
print("Chunks stored:", len(store.get()["ids"]))
print(store.similarity_search("Is delivery free during the festival sale?",
k=1)[0].page_content)
Output
%%writefile smartcart_rag_data.py
import os
import shutil
os.environ.setdefault("USER_AGENT", "SmartCartLab/1.0")

from langchain_community.document_loaders import (
    PyPDFLoader, Docx2txtLoader, WebBaseLoader, CSVLoader)
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_huggingface import HuggingFaceEmbeddings
from langchain_chroma import Chroma

DB_FOLDER = "smartcart_db_lab15"
SOURCES = [
    ("SmartCart_Return_Policy.pdf", "policy"),
    ("SmartCart_Delivery_FAQ.docx", "faq"),
    ("https://en.wikipedia.org/wiki/Cash_on_delivery", "web"),
    ("smartcart_products.csv", "product"),]

embedder = HuggingFaceEmbeddings(model_name="sentence-transformers/all-MiniLM-L6-v2")
Task 6 : Orchestrate the pipeline
Save the script
1
%%writefile smartcart_rag_data.py
import os
import shutil
os.environ.setdefault("USER_AGENT", "SmartCartLab/1.0")

from langchain_community.document_loaders import (
    PyPDFLoader, Docx2txtLoader, WebBaseLoader, CSVLoader)
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_huggingface import HuggingFaceEmbeddings
from langchain_chroma import Chroma

DB_FOLDER = "smartcart_db_lab15"
SOURCES = [
    ("SmartCart_Return_Policy.pdf", "policy"),
    ("SmartCart_Delivery_FAQ.docx", "faq"),
    ("https://en.wikipedia.org/wiki/Cash_on_delivery", "web"),
    ("smartcart_products.csv", "product"),]

embedder = HuggingFaceEmbeddings(model_name="sentence-transformers/all-MiniLM-L6-v2")

def load_documents():
    """Step 1 -- load every source and tag it with its doc_type."""
    docs = []
    for source, doc_type in SOURCES:
        if source.endswith(".pdf"):
            loader = PyPDFLoader(source)
        elif source.endswith(".docx"):
            loader = Docx2txtLoader(source)
        elif source.endswith(".csv"):
            loader = CSVLoader(source)
        else:
            loader = WebBaseLoader(source)
        for doc in loader.load():
            doc.metadata["doc_type"] = doc_type
            docs.append(doc)
    return docs

def chunk_documents(docs):
    """Step 2 -- split documents into overlapping chunks of up to 300 characters."""
    splitter = RecursiveCharacterTextSplitter(chunk_size=300,
                                              chunk_overlap=50)
    return splitter.split_documents(docs)

def build_vector_store(chunks):
    """Step 3 -- embed and store chunks in a fresh Chroma database."""
    shutil.rmtree(DB_FOLDER, ignore_errors=True)
    os.makedirs(DB_FOLDER, exist_ok=True)

    return Chroma.from_documents(
        documents=chunks,
        embedding=embedder,
        collection_name="smartcart",
        persist_directory=DB_FOLDER)
%%writefile smartcart_rag_data.py
import os
import shutil
os.environ.setdefault("USER_AGENT", "SmartCartLab/1.0")
from langchain_community.document_loaders import (
PyPDFLoader, Docx2txtLoader, WebBaseLoader, CSVLoader)
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_huggingface import HuggingFaceEmbeddings
from langchain_chroma import Chroma
DB_FOLDER = "smartcart_db_lab15"
SOURCES = [
("SmartCart_Return_Policy.pdf", "policy"),
("SmartCart_Delivery_FAQ.docx", "faq"),
("https://en.wikipedia.org/wiki/Cash_on_delivery", "web"),
("smartcart_products.csv", "product"),]
embedder = HuggingFaceEmbeddings(model_name="sentence-transformers/all-MiniLM-L6-v2")
def load_documents():
"""Step 1 -- load every source and tag it with its doc_type."""
docs = []
for source, doc_type in SOURCES:
if source.endswith(".pdf"):
loader = PyPDFLoader(source)
elif source.endswith(".docx"):
loader = Docx2txtLoader(source)
elif source.endswith(".csv"):
loader = CSVLoader(source)
else:
loader = WebBaseLoader(source)
for doc in loader.load():
doc.metadata["doc_type"] = doc_type
docs.append(doc)
return docs
def chunk_documents(docs):
"""Step 2 -- split documents into overlapping chunks of up to 300 characters."""
splitter = RecursiveCharacterTextSplitter(chunk_size=300,
chunk_overlap=50)
return splitter.split_documents(docs)
def build_vector_store(chunks):
"""Step 3 -- embed and store chunks in a fresh Chroma database."""
shutil.rmtree(DB_FOLDER, ignore_errors=True)
os.makedirs(DB_FOLDER, exist_ok=True)
return Chroma.from_documents(
documents=chunks,
embedding=embedder,
collection_name="smartcart",
persist_directory=DB_FOLDER)
def get_retriever(k=3, doc_type=None):
"""Step 4 -- open the saved database and return a retriever."""
store = Chroma(collection_name="smartcart",
embedding_function=embedder,
persist_directory=DB_FOLDER)
search_kwargs = {"k": k}
if doc_type:
search_kwargs["filter"] = {"doc_type": doc_type}
return store.as_retriever(search_kwargs=search_kwargs)
if __name__ == "__main__":
docs = load_documents()
print("Loaded ", len(docs), "documents")
chunks = chunk_documents(docs)
print("Created", len(chunks), "chunks")
build_vector_store(chunks)
print("Stored in", DB_FOLDER)Run the script
2
%run smartcart_rag_data.py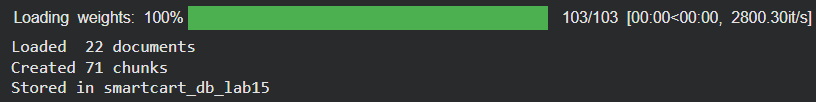
Output
import pandas as pd
from smartcart_rag_data import get_retriever

retriever = get_retriever(k=3)

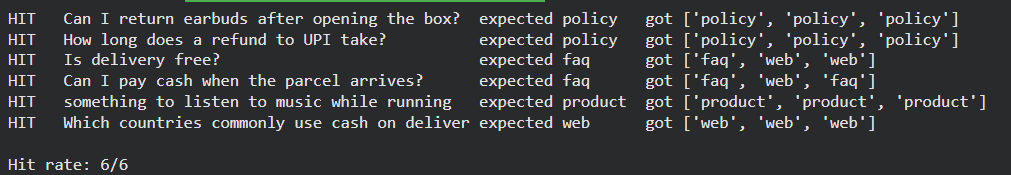
tests = [
    ("Can I return earbuds after opening the box?", "policy"),
    ("How long does a refund to UPI take?", "policy"),
    ("Is delivery free?", "faq"),
    ("Can I pay cash when the parcel arrives?", "faq"),
    ("something to listen to music while running", "product"),
    ("Which countries commonly use cash on delivery?", "web"),]

rows = []
for question, expected in tests:
    found = [doc.metadata["doc_type"] for doc in retriever.invoke(question)]
    hit = expected in found
    rows.append({"question": question, "expected": expected, "found": found, "hit": hit})
    print(f"{'HIT ' if hit else 'MISS'}  {question[:44]:<44} expected {expected:<8} got {found}")

results = pd.DataFrame(rows)
results.to_csv("smartcart_retrieval_test.csv", index=False)
print(f"\nHit rate: {results['hit'].sum()}/{len(results)}")
Task 7 : Test the Retrieval
Run the retrieval test
1
Output
faq_retriever = get_retriever(k=1, doc_type="faq")
print(faq_retriever.invoke("Can I pay cash when the parcel arrives?")[0].page_content)
Fix the metadata filter from Task 4
2
Output

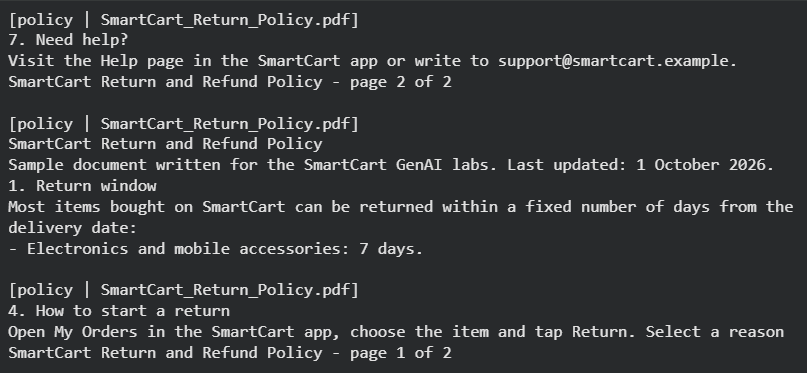
for doc in retriever.invoke("What is SmartCart's return policy for opened electronics?"):
    print(f"[{doc.metadata['doc_type']} | {doc.metadata['source']}]")
    print(doc.page_content, "\n")
Retrieve the answer to test T8, the question which was dodged since Lab10
3
Output
Great job!
You have successfully explored the RAG ingestion, retrieval, and generation. Loaded PDF, Word, web, and CSV data into LangChain documents, compared chunking methods, and stored and searched chunks in Chroma with metadata filters. You compared Chroma with FAISS, reloaded and updated the saved index, built smartcart_rag_data.py, measured retrieval hit rate.
Checkpoint
Git Push
git push origin branchNameNext-Lab Preparation
Topic : Build Chatbot V3 - Full RAG Integration
1) Generation of RAG
2) Grounded Answers
3) Citing Sources